Jonas Foster · 29 October 2026
Exploring Reinforcement Learning Applications for Dynamic Data Retention Policies in Distributed Cache Networks
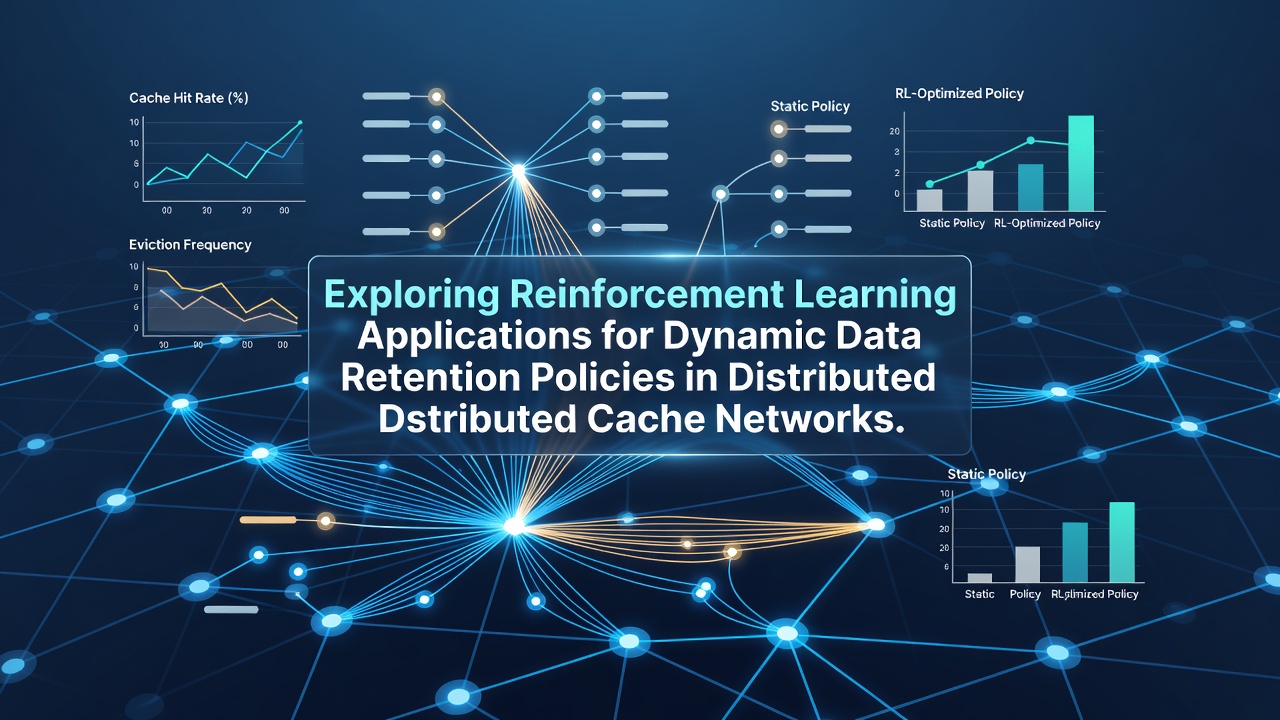
Researchers have applied reinforcement learning techniques to optimize data retention policies across distributed cache networks since the early 2020s, and these methods continue to evolve with new deployments reported through October 2026. The core idea involves training agents to decide which data blocks to retain or evict by processing real-time signals such as request frequency, network latency, and storage costs. Agents learn policies that maximize cache hit rates while minimizing unnecessary data movement between nodes. Distributed cache systems spread data across multiple servers to reduce access delays, yet static retention rules often fail when traffic patterns shift suddenly. Reinforcement learning addresses this limitation by letting agents interact with the environment and update their decision models continuously. Studies from academic groups in Canada indicate that deep Q-network variants can reduce eviction errors by 18 to 25 percent compared with least-recently-used baselines in simulated multi-region setups.Core Mechanisms in Reinforcement Learning for Cache Retention
Agents receive state representations that include current cache occupancy levels, historical access sequences, and inter-node bandwidth availability. Actions consist of retaining a block, evicting it, or migrating it to another cache tier. Rewards combine positive signals for successful hits with penalties for latency spikes or excessive data transfers. Over repeated episodes the policy converges toward decisions that balance short-term hit rates against long-term storage efficiency.
Policy gradient methods such as proximal policy optimization allow agents to explore retention strategies without requiring labeled datasets of optimal decisions. In practice, training occurs offline on historical traces collected from production networks, after which the resulting models run online with periodic fine-tuning. Observers note that this hybrid approach keeps computational overhead low enough for edge nodes with limited processing capacity.
Deployment Patterns Across Network Architectures
Large-scale content delivery networks have integrated reinforcement learning modules into their cache controllers to handle regional traffic surges. One documented implementation in European research testbeds used multi-agent reinforcement learning so that each geographic cluster maintained its own policy while sharing aggregated state information. Data shows coordination between agents lowered cross-region data fetches during peak events by measurable margins.
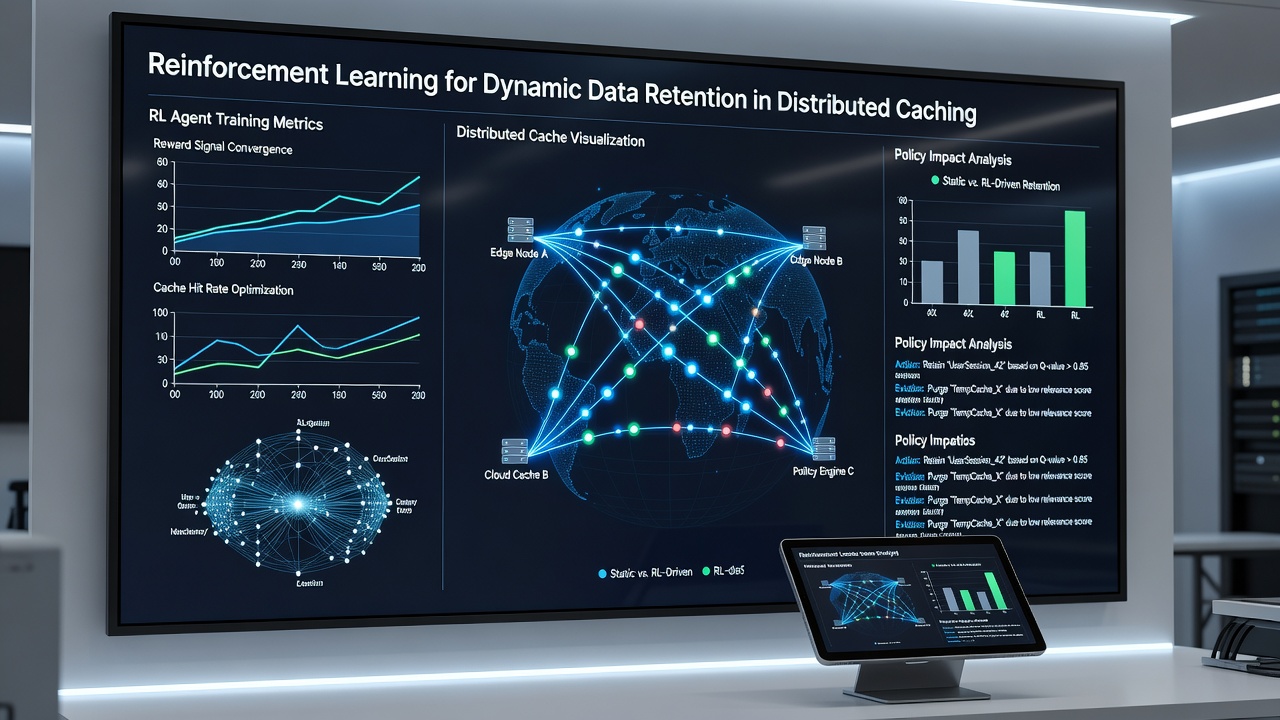
Cloud providers in Australia have tested similar frameworks on object storage layers that serve machine learning workloads. Retention decisions there incorporate not only access frequency but also predicted future demand derived from training job schedules. Results reported in conference proceedings indicate improved resource utilization during batch processing windows.
Integration with Existing Cache Protocols
Reinforcement learning policies often sit alongside established protocols such as HTTP caching directives and custom eviction hooks. The learning layer overrides default behavior only when confidence thresholds are met, which prevents disruptive changes during initial rollout phases. Engineers at several institutions have published interface specifications that allow third-party agents to plug into popular cache software stacks without altering core packet handling logic.
Monitoring dashboards track reward accumulation alongside traditional metrics like hit ratio and bandwidth consumption. When reward trends diverge from hit-rate trends, operators receive alerts that prompt policy review or additional training iterations. This feedback loop keeps the system aligned with evolving service-level objectives.
Challenges Encountered in Production Environments
Exploration noise during training can temporarily degrade performance if agents test suboptimal retention choices on live traffic. Mitigation strategies include safe exploration constraints and shadow-mode evaluation where proposed actions are logged but not executed until validated. Research groups in Asia have documented techniques that bound performance loss during online learning phases to under 5 percent.
State space complexity grows quickly when networks span dozens of nodes and thousands of data objects. Dimensionality reduction through autoencoders or graph neural networks has proven effective at compressing representations while preserving decision-critical features. Continued work on sample-efficient algorithms remains active as of late 2026.
Conclusion
Reinforcement learning supplies a data-driven pathway for managing retention policies in distributed caches where manual tuning proves impractical. Implementations continue to appear in both academic testbeds and commercial infrastructures, supported by ongoing refinements in multi-agent coordination and safe learning methods. The trajectory through October 2026 points toward wider adoption as training infrastructure becomes more accessible and integration standards mature.